Predicting what a compiler outputs is quiet hard, especially if you enable optimization flags or get near any undefined behavior. But I think you’re right to say that a compiler is more predictable than any LLM.
I don’t get the point why you should be unable to audit the output of an LLM? If its used as a tool like described the user should have the knowlage to audit any output
Then I can run it again, and the output will be the same.
I can run a LLM prompt.
Then I can run it again, and the output should not be the same. The unpredictability is what makes the tech great - Nobody in decision making actually understands this, but the goal is not for identical outputs. Just like me and you, don’t respond to the same question in the same way every time
Compilers aren’t all that deterministic without effort. Example, both gc and clang if ran with parallelism can produce different results purely off file system lookup differences alone. This means intermediate archive files can be equivalent in content from the perspective of functions built but differ in order. This can easily filter up to the final binary being different. Making compilers bitwise deterministic is a lot more effort than running the same compiler on the same input. This is ignoring things like timestamps and other common sources of non determinism. But I can say the Debian reproducible build project has most of this figured out but compilers are not as deterministic as your comment implies. They can be, but you should really check that your final binary is bit for but the same. If you’ve used any parallelism it likely isn’t.
If we then bring in lto et al it gets worse.
Let’s take just gcc, are you setting -frandom-seed, SOURCE_DATE_EPOCH, -file-prefix-map, are you ensuring the input file list is deterministic? If you’ve used any can’t affirm yes to at least these 4, note these are just the things I can remember, you do not have a deterministic compile chain.
But I rarely want the output twice? At least in this domain of coding, the entire point is doing it once.
Secondly, I can definitely validate it in most ways that matter. Ironically, by compiling it for example, I make 100% certain the output was well defined code. Type checking, linting, tests, etc. all help ensure I got functionally valid code.
At that point I might not really care if the function name or a variable name is different, just like I don’t care that the compiler did some kind of heuristic optimization or minified the names or something.
In both cases, I have a target functionality, and I need to validate it was reached. The way I got there doesn’t matter (in most cases).
It’s a bit like Docker vs. Nix. Sure, docker isn’t really reproducible perfectly, but it fulfills it’s goal for most people most of the time for a fraction of the time and effort taken.

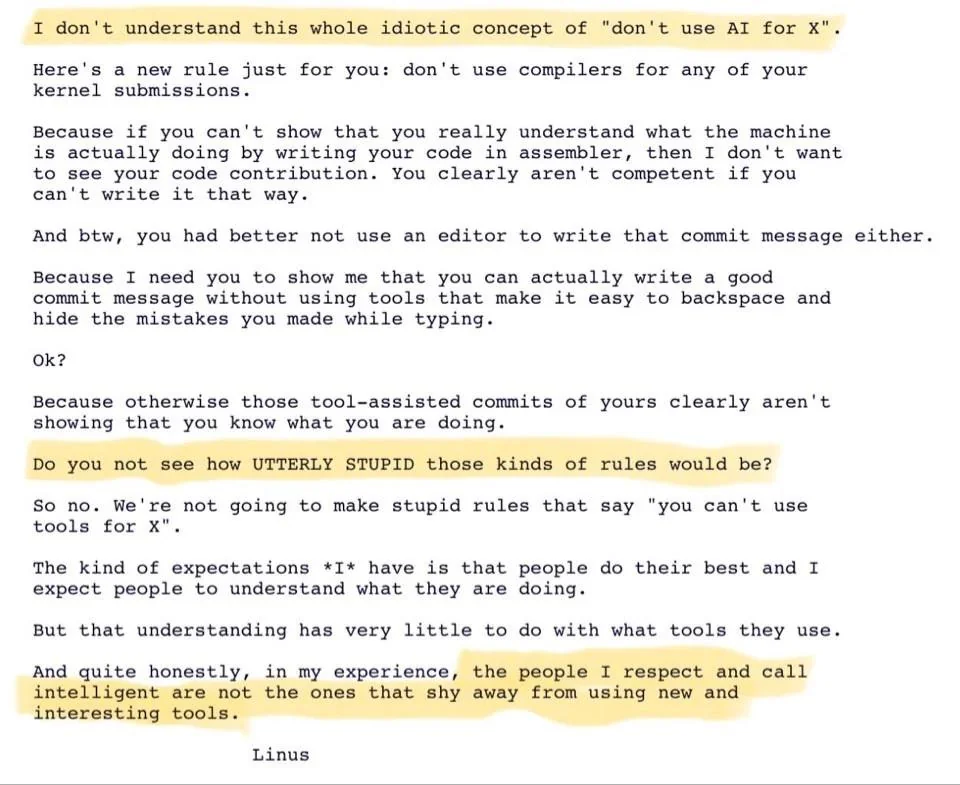
Predicting what a compiler outputs is quiet hard, especially if you enable optimization flags or get near any undefined behavior. But I think you’re right to say that a compiler is more predictable than any LLM. I don’t get the point why you should be unable to audit the output of an LLM? If its used as a tool like described the user should have the knowlage to audit any output
I can run a compiler.
Then I can run it again, and the output will be the same.
I can run a LLM prompt.
Then I can run it again, and the output should not be the same. The unpredictability is what makes the tech great - Nobody in decision making actually understands this, but the goal is not for identical outputs. Just like me and you, don’t respond to the same question in the same way every time
Compilers aren’t all that deterministic without effort. Example, both gc and clang if ran with parallelism can produce different results purely off file system lookup differences alone. This means intermediate archive files can be equivalent in content from the perspective of functions built but differ in order. This can easily filter up to the final binary being different. Making compilers bitwise deterministic is a lot more effort than running the same compiler on the same input. This is ignoring things like timestamps and other common sources of non determinism. But I can say the Debian reproducible build project has most of this figured out but compilers are not as deterministic as your comment implies. They can be, but you should really check that your final binary is bit for but the same. If you’ve used any parallelism it likely isn’t.
If we then bring in lto et al it gets worse.
Let’s take just gcc, are you setting -frandom-seed, SOURCE_DATE_EPOCH, -file-prefix-map, are you ensuring the input file list is deterministic? If you’ve used any can’t affirm yes to at least these 4, note these are just the things I can remember, you do not have a deterministic compile chain.
But I rarely want the output twice? At least in this domain of coding, the entire point is doing it once.
Secondly, I can definitely validate it in most ways that matter. Ironically, by compiling it for example, I make 100% certain the output was well defined code. Type checking, linting, tests, etc. all help ensure I got functionally valid code.
At that point I might not really care if the function name or a variable name is different, just like I don’t care that the compiler did some kind of heuristic optimization or minified the names or something.
In both cases, I have a target functionality, and I need to validate it was reached. The way I got there doesn’t matter (in most cases).
It’s a bit like Docker vs. Nix. Sure, docker isn’t really reproducible perfectly, but it fulfills it’s goal for most people most of the time for a fraction of the time and effort taken.
At least clean it up so it’s maintainable, introducing tech debt is a long term impact
For local LLMs you can set the seed and generate the same output every time.
You can get the same output from the LLM if you put the appropriate guardrails and context in place. That’s what is happening in the enterprise space.
I was just pointing out Linus was conflating the two to make his point. I don’t agree with this, but everything else he said was fine.
100%, or we’d commit prompts instead of code lol